Accepted to WACV 2027
Scale-Wise VAR
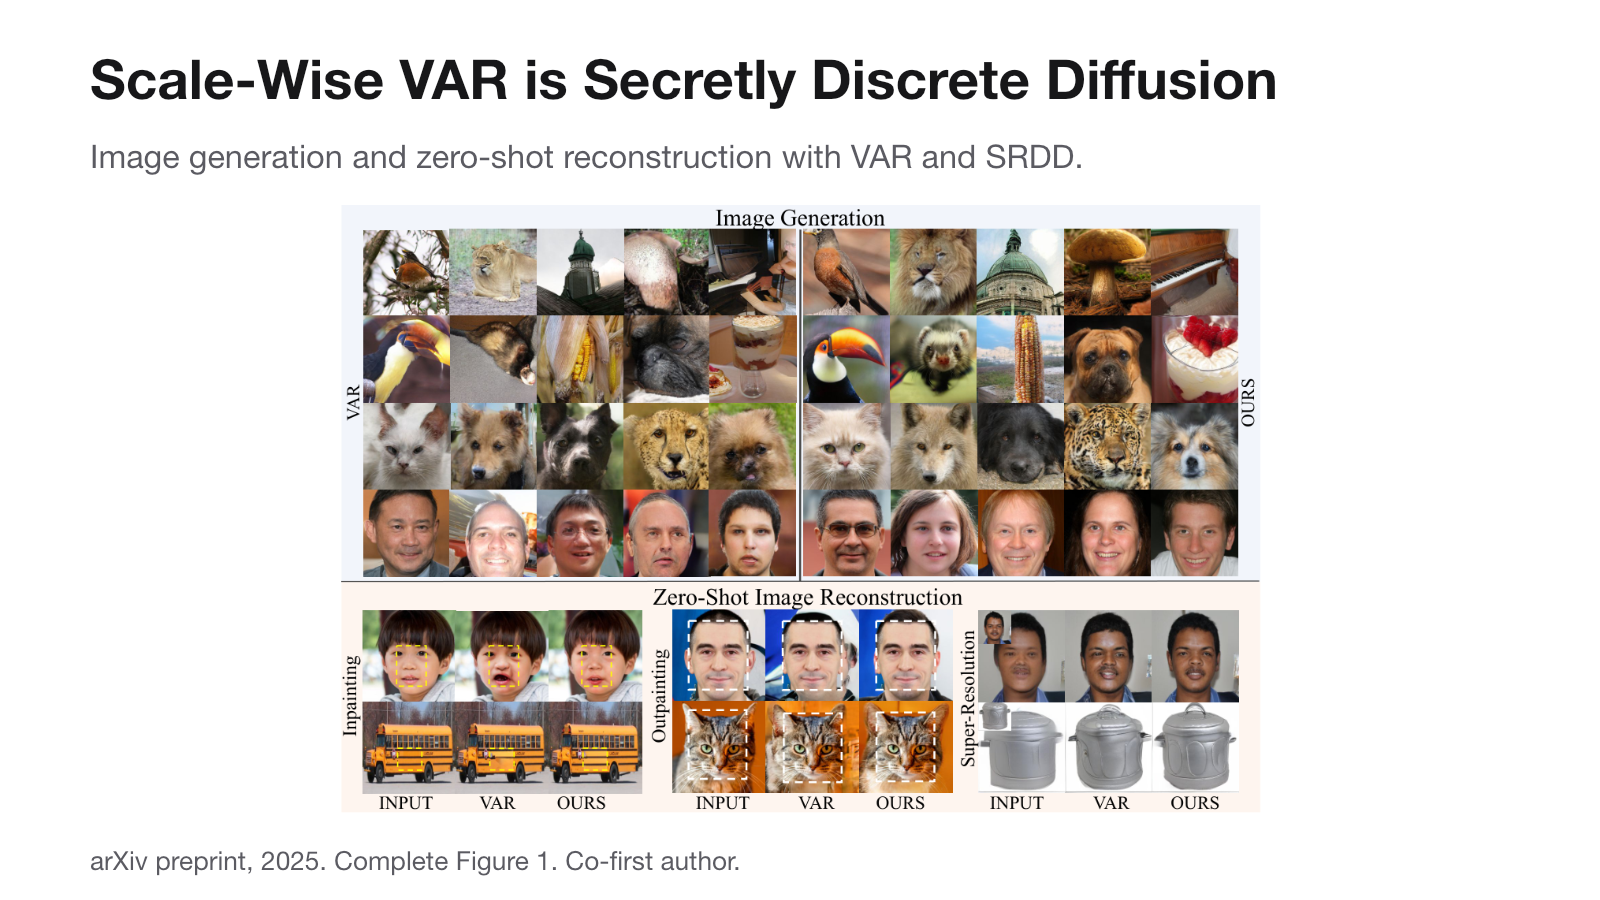
Show how a particular scale-by-scale image generator can behave like a diffusion model, allowing it to refine its predictions.
Co-first author
Generated images
Outpainting
Super-resolution
How it works
-
Express next-scale prediction as a transition between discrete visual-token representations.
-
Apply the Markovian attention mask and relate the resulting transitions and training objective to discrete diffusion.
-
Use this interpretation in Scalable Visual Refinement with Discrete Diffusion (SRDD) to bring iterative refinement into the scale-wise generation framework.
The autoregression–diffusion connection
Scale-wise generation as discrete diffusion
Scale-wise VAR generates visual tokens from coarse scales to finer scales. This work shows that, under a Markovian attention mask, its generation process is mathematically equivalent to a discrete diffusion process.
The attention-mask condition is central to the equivalence. It provides a principled way to connect autoregressive token prediction with diffusion-style refinement.
Results
The comparison uses a matched 200-epoch training study across four benchmarks. Lower FID indicates closer agreement between generated and reference image distributions.
| Dataset | Generation | VAR | SRDD |
|---|---|---|---|
| MiniImageNet | Conditional | 21.01 | 16.76 |
| SUN | Conditional | 15.72 | 13.26 |
| FFHQ | Unconditional | 19.23 | 17.37 |
| AFHQ | Unconditional | 14.74 | 13.14 |
Scale-Wise VAR, arXiv preprint 2025, Table 1
MiniImageNet FID decreases by 20.2% relative to VAR.
The equivalence requires a Markovian attention mask. These results are from the 2025 preprint, and MiniImageNet is a reduced benchmark.
Presentation