Nithin Gopalakrishnan Nair
I am a Research Engineer at Apple, where I work on long-horizon agents for human interaction understanding and the simulation and evaluation infrastructure used to develop them. I completed my Ph.D. in Electrical and Computer Engineering at Johns Hopkins University, working under the supervision of Dr. Vishal M. Patel at the VIU Lab. Prior to JHU, I obtained my dual degree (B.Tech & M.Tech) in Electrical Engineering from the Indian Institute of Technology Madras, where I conducted research on image reconstruction with Dr. A.N. Rajagopalan at the IPCV Lab.
My research spans large-scale model training, generative modeling, multimodal learning, synthetic data, and 3D understanding. During my Ph.D., I worked on controlling and composing diffusion models and improving generalization with synthetic data.
I find the theory behind diffusion models fascinating. Fun fact: the basics were proposed by Einstein! Over the past several years, I have contributed to advances in image, video, and 3D generation using these models. I welcome collaborations with researchers who share an interest in generative modeling. Please feel free to reach out.
-
WACV 2027
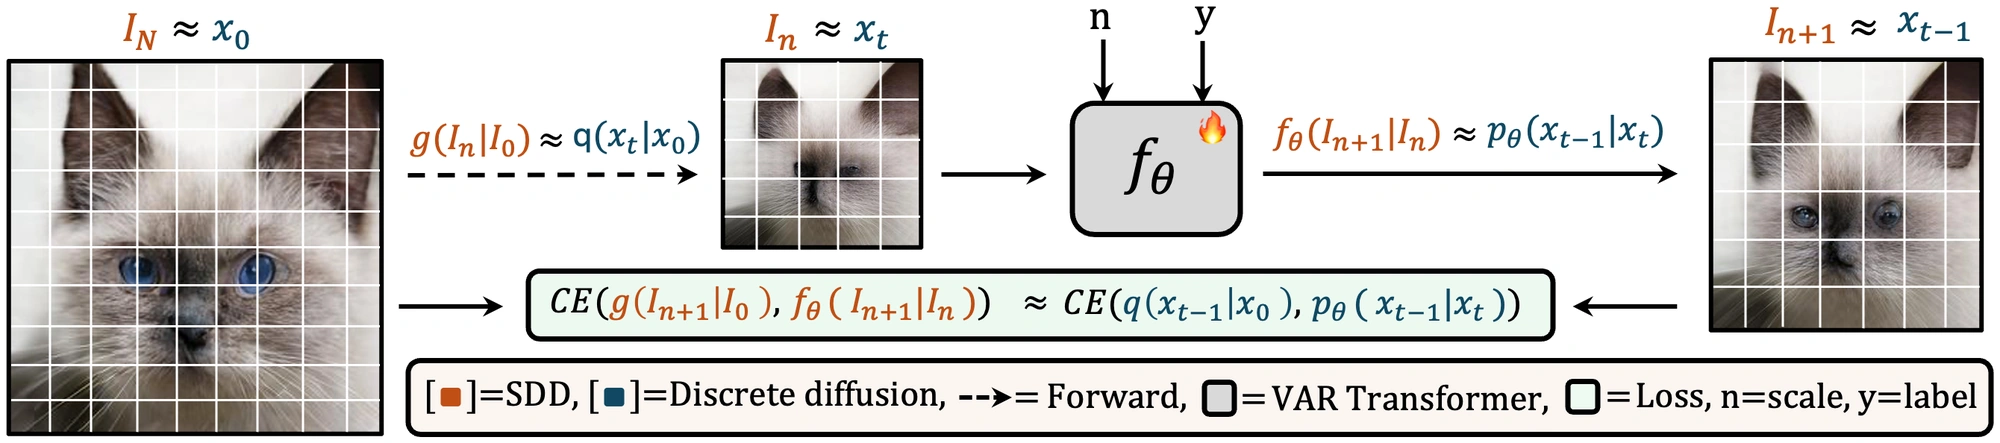
Scale-wise VAR is Secretly Discrete Diffusion
In Winter Conference on Applications of Computer Vision (WACV), 2027Accepted in 2026; forthcoming.Paper Slides CodeAbstract & citation
Visual Autoregressive (VAR) models have recently emerged as a powerful alternative to diffusion models for high-quality image generation. The VAR architecture generates visual tokens in a coarse-to-fine, scale-by-scale manner, which sets it apart from traditional raster-order autoregressive models. However, the inner mechanism behind VAR model’s effectiveness is under-explored. In this paper, we present a novel perspective on VAR: we show that VAR models can be viewed through the lens of discrete diffusion models. Specifically, we demonstrate that VAR’s generative process is functionally equivalent to a scale-wise discrete masked diffusion process, with slight variation in the learning objective. In this framework, VAR’s next-scale predictions correspond to masked token recovery in a multi-scale latent space. Our findings reveal a deep connection between autoregressive visual generation and diffusion processes, offering new theoretical insights and opening the door for further exploration of hybrid generative architectures.
@inproceedings{kumar2025scale, title = {Scale-wise VAR is Secretly Discrete Diffusion}, author = {Kumar, Amandeep and Nair, Nithin Gopalakrishnan and Patel, Vishal M}, booktitle = {Winter Conference on Applications of Computer Vision (WACV)}, year = {2027}, note = {Accepted in 2026; forthcoming.}, } -
ICCV 2025
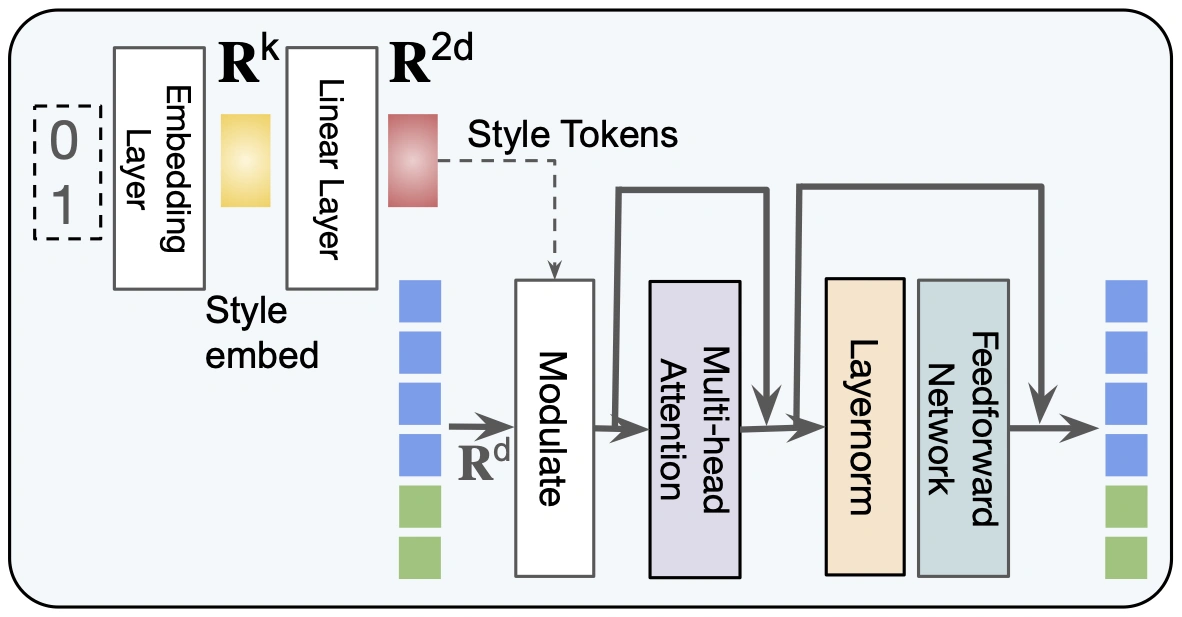
Scaling Transformer-Based Novel View Synthesis Models with Token Disentanglement and Synthetic Data
In Proceedings of the IEEE/CVF International Conference on Computer Vision, 2025Paper Slides Project siteAbstract & citation
Large transformer-based models have made significant progress in generalizable novel view synthesis (NVS) from sparse input views, generating novel viewpoints without the need for test-time optimization. However, these models are constrained by the limited diversity of publicly available scene datasets, making most real-world (in-the-wild) scenes out-of-distribution. To overcome this, we incorporate synthetic training data generated from diffusion models, which improves generalization across unseen domains. While synthetic data offers scalability, we identify artifacts introduced during data generation as a key bottleneck affecting reconstruction quality. To address this, we propose a token disentanglement process within the transformer architecture, enhancing feature separation and ensuring more effective learning. This refinement not only improves re-construction quality over standard transformers but also enables scalable training with synthetic data. As a result, our method outperforms existing models on both in-dataset and cross-dataset evaluations, achieving state-of-the-art results across multiple benchmarks while significantly reducing computational costs
@inproceedings{nair2025scaling, title = {Scaling Transformer-Based Novel View Synthesis Models with Token Disentanglement and Synthetic Data}, author = {Nair, Nithin Gopalakrishnan and Kaza, Srinivas and Luo, Xuan and Patel, Vishal M and Lombardi, Stephen and Park, Jungyeon}, booktitle = {Proceedings of the IEEE/CVF International Conference on Computer Vision}, pages = {28567--28576}, year = {2025}, archiveprefix = {arXiv}, primaryclass = {cs.GR}, selected = true, eprint = {2509.06950}, url = {https://scaling3dnvs.github.io/}, } -
CVPR 2025
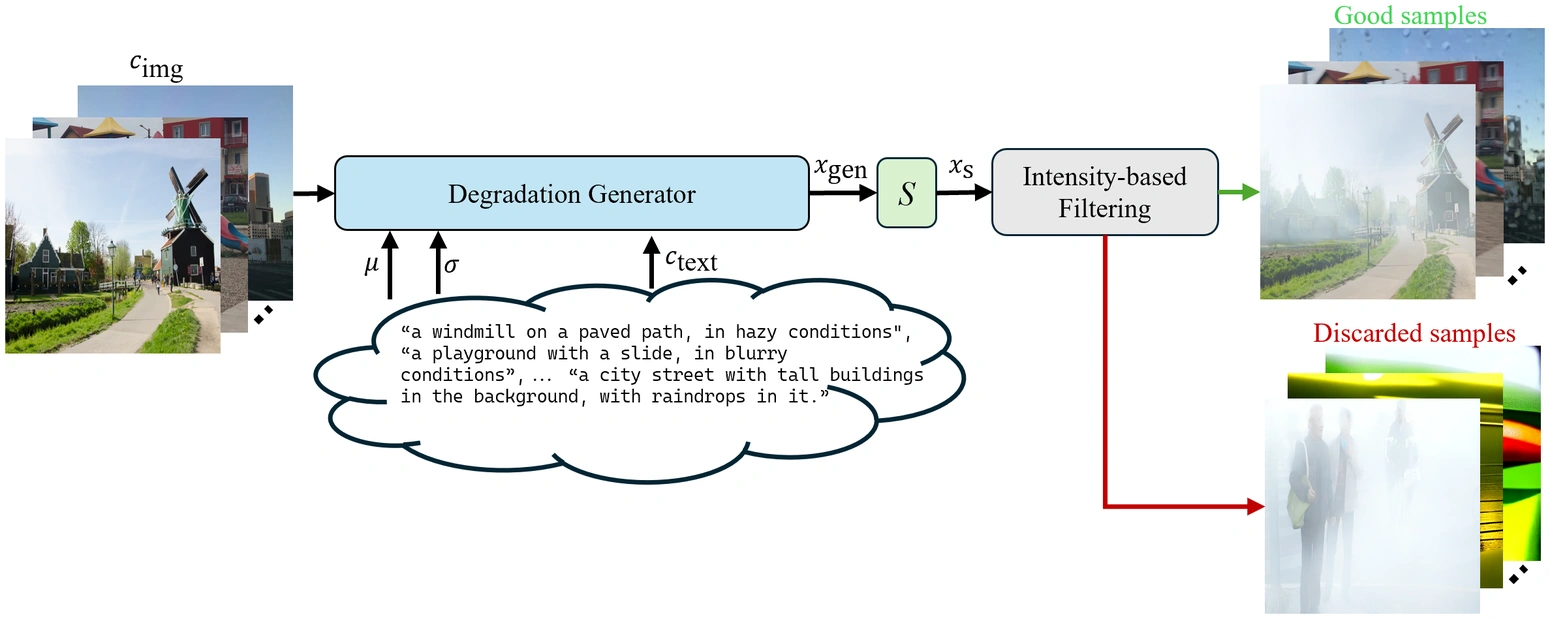
GenDeg: Diffusion-based Degradation Synthesis for Generalizable All-in-One Image Restoration
In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2025Paper Slides CodeAbstract & citation
Deep learning-based models for All-In-One image Restoration (AIOR) have achieved significant advancements in recent years. However, their practical applicability is limited by poor generalization to samples outside the training distribution. This limitation arises primarily from insufficient diversity in degradation variations and scenes within existing datasets. In this paper, we leverage the generative capabilities of latent diffusion models to synthesize high-quality degraded images from their clean counterparts. Specifically, we introduce GenDeg, a degradation and intensity-aware conditional diffusion model, capable of producing diverse degradation patterns on clean images. Using GenDeg, we synthesize over 550k samples across six degradation types: haze, rain, snow, motion blur, low-light, and raindrops. These generated samples are integrated with existing datasets to form the GenDS dataset, comprising over 750k samples. Our experiments reveal that image restoration models trained on GenDS dataset exhibit significant improvements in out-of-distribution performance.
@inproceedings{rajagopalan2025gendeg, title = {GenDeg: Diffusion-based Degradation Synthesis for Generalizable All-in-One Image Restoration}, author = {Rajagopalan, Sudarshan and Nair, Nithin Gopalakrishnan and Paranjape, Jay N and Patel, Vishal M}, booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition}, pages = {28144--28154}, year = {2025}, selected = true, url = {https://sudraj2002.github.io/gendegpage/}, } -
ECCV 2024
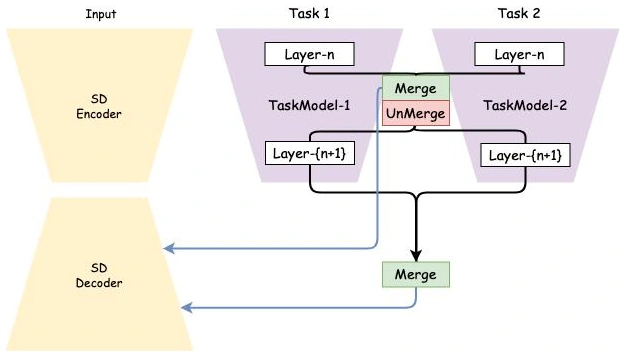
Maxfusion: Plug&play multi-modal generation in text-to-image diffusion models
In European Conference on Computer Vision, 2024Paper Slides Project siteAbstract & citation
Large diffusion-based Text-to-Image (T2I) models have shown impressive generative powers for text-to-image generation as well as spatially conditioned image generation. For most applications, we can train the model end-to-end with paired data to obtain photorealistic generation quality. However, to add an additional task, one often needs to retrain the model from scratch using paired data across all modalities to retain good generation performance. In this paper, we tackle this issue and propose a novel strategy to scale a generative model across new tasks with minimal compute. During our experiments, we discovered that the variance maps of intermediate feature maps of diffusion models capture the intensity of conditioning. Utilizing this prior information, we propose MaxFusion, an efficient strategy to scale up text-to-image generation models to accommodate new modality conditions. Specifically, we combine aligned features of multiple models, hence bringing a compositional effect. Our fusion strategy can be integrated into off-the-shelf models to enhance their generative prowess. We show the effectiveness of our method by utilizing off-the-shelf models for multi-modal generation.
@inproceedings{nair2025maxfusion, title = {Maxfusion: Plug\&play multi-modal generation in text-to-image diffusion models}, author = {Nair, Nithin Gopalakrishnan and Valanarasu, Jeya Maria Jose and Patel, Vishal M}, booktitle = {European Conference on Computer Vision}, pages = {93--110}, year = {2024}, selected = true, } -
CVPR 2024
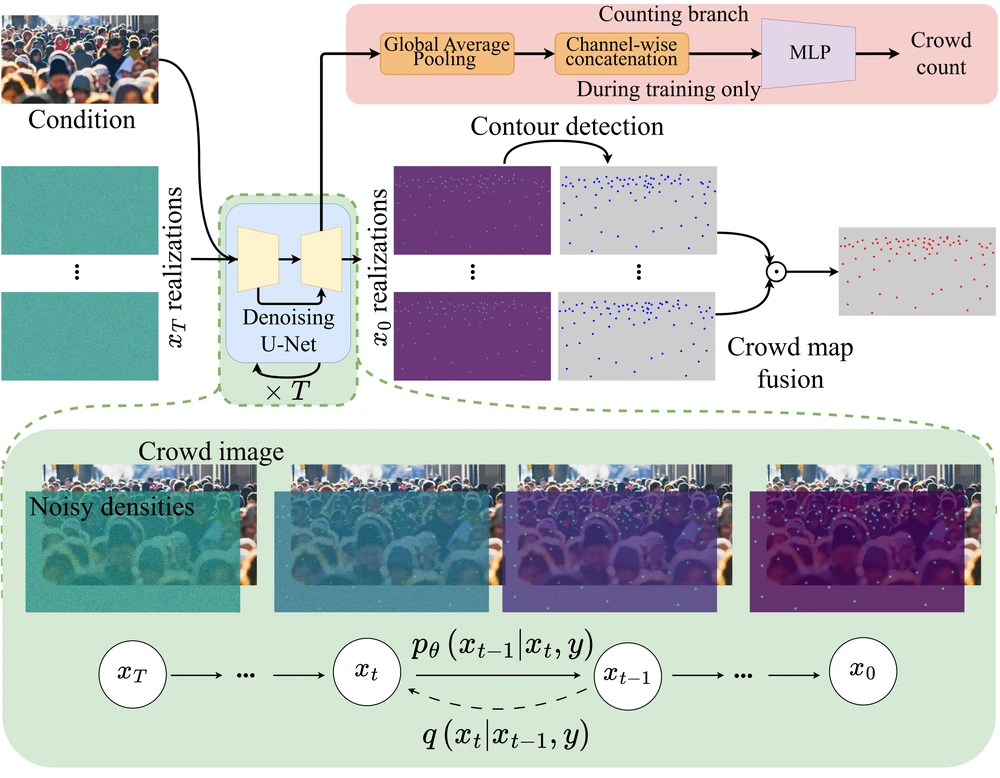
Diffuse-Denoise-Count: Accurate Crowd-Counting with Diffusion Models
In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Mar 2024Paper Slides CodeAbstract & citation
Crowd counting is a key aspect of crowd analysis and has been typically accomplished by estimating a crowd density map and summing over the density values. However, this approach suffers from background noise accumulation and loss of density due to the use of broad Gaussian kernels to create the ground truth density maps. This issue can be overcome by narrowing the Gaussian kernel. However, existing approaches perform poorly when trained with such ground truth density maps. To overcome this limitation, we propose using conditional diffusion models to predict density maps, as diffusion models are known to model complex distributions well and show high fidelity to training data during crowd-density map generation. Furthermore, as the intermediate time steps of the diffusion process are noisy, we incorporate a regression branch for direct crowd estimation only during training to improve the feature learning. In addition, owing to the stochastic nature of the diffusion model, we introduce producing multiple density maps to improve the counting performance contrary to the existing crowd counting pipelines. Further, we also differ from the density summation and introduce contour detection followed by summation as the counting operation, which is more immune to background noise. We conduct extensive experiments on public datasets to validate the effectiveness of our method. Specifically, our novel crowd-counting pipeline improves the error of crowd-counting by up to 6 percent on JHU-CROWD++ and up to 7 percent on UCF-QNRF.
@inproceedings{ranasinghe2024diffuse, title = {Diffuse-Denoise-Count: Accurate Crowd-Counting with Diffusion Models}, author = {Ranasinghe, Yasiru and Nair, Nithin Gopalakrishnan and Bandara, Wele Gedara Chaminda and Patel, Vishal M}, booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition}, month = mar, year = {2024}, url = {https://dylran.github.io/crowddiff.github.io/}, } -
ICCV 2023
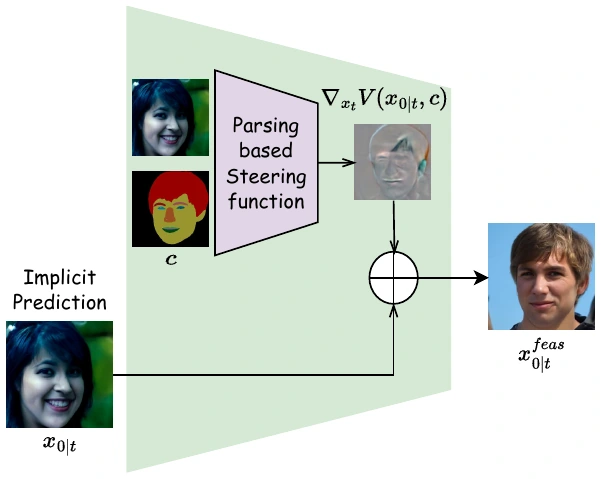
Steered Diffusion: A Generalized Framework for Plug-and-Play Conditional Image Synthesis
In Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV), Oct 2023Paper Slides CodeAbstract & citation
Conditional generative models typically demand large annotated training sets to achieve high-quality synthesis. As a result, there has been significant interest in designing models that perform plug-and-play generation, i.e., to use a predefined or pretrained model, which is not explicitly trained on the generative task, to guide the generative process (e.g., using language). However, such guidance is typically useful only towards synthesizing high-level semantics rather than editing fine-grained details as in image-to-image translation tasks. To this end, and capitalizing on the powerful fine-grained generative control offered by the recent diffusion-based generative models, we introduce Steered Diffusion, a generalized framework for photorealistic zero-shot conditional image generation using a diffusion model trained for unconditional generation. The key idea is to steer the image generation of the diffusion model at inference time via designing a loss using a pre-trained inverse model that characterizes the conditional task. This loss modulates the sampling trajectory of the diffusion process. Our framework allows for easy incorporation of multiple conditions during inference. We present experiments using steered diffusion on several tasks including inpainting, colorization, text-guided semantic editing, and image super-resolution. Our results demonstrate clear qualitative and quantitative improvements over state-of-the-art diffusion-based plug-and-play models while adding negligible additional computational cost.
@inproceedings{Nair_2023_ICCV, author = {Nair, Nithin Gopalakrishnan and Cherian, Anoop and Lohit, Suhas and Wang, Ye and Koike-Akino, Toshiaki and Patel, Vishal M. and Marks, Tim K.}, title = {Steered Diffusion: A Generalized Framework for Plug-and-Play Conditional Image Synthesis}, booktitle = {Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV)}, month = oct, year = {2023}, pages = {20850-20860}, selected = true, } -
CVPR 2023
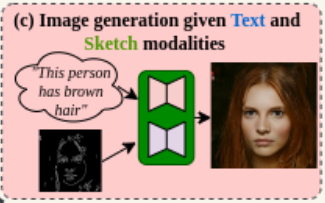
Unite and Conquer: Plug & Play Multi-Modal Synthesis Using Diffusion Models
In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Jun 2023Paper Slides CodeAbstract & citation
Generating photos satisfying multiple constraints finds broad utility in the content creation industry. A key hurdle to accomplishing this task is the need for paired data consisting of all modalities (i.e., constraints) and their corresponding output. Moreover, existing methods need retraining using paired data across all modalities to introduce a new condition. This paper proposes a solution to this problem based on denoising diffusion probabilistic models (DDPMs). Our motivation for choosing diffusion models over other generative models comes from the flexible internal structure of diffusion models. Since each sampling step in the DDPM follows a Gaussian distribution, we show that there exists a closed-form solution for generating an image given various constraints. Our method can unite multiple diffusion models trained on multiple sub-tasks and conquer the combined task through our proposed sampling This CVPR paper is the Open Access version, provided by the Computer Vision Foundation. Except for this watermark, it is identical to the accepted version; the final published version of the proceedings is available on IEEE Xplore. 6070 strategy. We also introduce a novel reliability parameter that allows using different off-the-shelf diffusion models trained across various datasets during sampling time alone to guide it to the desired outcome satisfying multiple constraints. We perform experiments on various standard multimodal tasks to demonstrate the effectiveness of our approach. More details can be found at: https://nithingk.github.io/projectpages/Multidiff
@inproceedings{nair2023unite,
  title = {Unite and Conquer: Plug \& Play Multi-Modal Synthesis Using Diffusion Models},
  author = {Nair, Nithin Gopalakrishnan and Bandara, Wele Gedara Chaminda and Patel, Vishal M},
  booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition},
  month = jun,
  pages = {6070--6079},
  year = {2023},
  selected = true,
}